Maintenance data standardization is the practice of enforcing a consistent data model and code lists for work orders, assets, failures, and timestamps so KPIs like MTBF and MTTR become reliable across sites. Without it, teams compare numbers that were never calculated the same way twice. With it, maintenance managers get benchmarks they can act on. The steps that follow turn that principle into a working roadmap.
TL;DR:
- Standardizing maintenance data requires consistent asset IDs, failure codes, timestamps, and units to ensure reliable KPI calculations across sites.
- Inconsistent coding and missing timestamps distort key metrics like MTBF and MTTR, leading to inaccurate benchmarking and poor decision-making.
- Established standards such as ISO 14224 and SMRP metrics provide proven frameworks for creating a cross-industry, reliable maintenance data model.
- Common data quality issues include overlapping codes, free-text notes, and poorly organized code lists, which hinder effective standardization efforts.
- Implementing a phased approach with clear KPI targets, technician training, and validation tools improves data quality and supports sustainable standardization.
Table of Contents
- What Maintenance Data Standardization Actually Covers
- Why Inconsistent Data Breaks MTBF, MTTR, and Benchmarking
- Standards and Reference Models Worth Building On
- Common Data Quality Problems That Block Standardization
- Step-by-Step Implementation Roadmap
- Cleaning Up Legacy Maintenance Data for Analytics
- Governance That Keeps Standards From Decaying
- How CMMS Features Support the Standardization Roadmap
- What a Realistic Standardization Timeline Looks Like
- Getting Help Implementing a Standardization Program
- Sources
- FAQ
What Maintenance Data Standardization Actually Covers
Standardization means every work order, no matter who fills it out or where, uses the same fields, the same units, and the same code lists. That consistency is what makes aggregation possible in the first place.
A workable minimal data model includes:
- Asset ID and taxonomy: a unique identifier tied to a consistent equipment classification, not a site-specific nickname.
- Location hierarchy: plant, area, line, and asset, structured the same way everywhere.
- Event type: preventive, corrective, inspection, or condition-based, using one shared list.
- Failure code: a controlled vocabulary for failure mode, not a free-text guess.
- Timestamps: open and close times recorded in the same format and time zone.
- Labor, hours, parts, and costs: logged in matching units so totals actually add up.
Picture three technicians closing similar jobs. One logs “bearing failure,” another “BRG FAIL,” a third leaves the field blank and writes a note instead. None of those roll up into the same failure category, and any KPI built on failure counts is already wrong before analysis starts. Standard units matter just as much: mixing hours and days in downtime fields, or dollars and local currency in cost fields, silently corrupts every average calculated from them.
Why Inconsistent Data Breaks MTBF, MTTR, and Benchmarking
MTBF and MTTR are only as good as the timestamps and failure codes feeding them. When one site logs “unplanned failure” and another logs “breakdown” for the same event, the failure count splits across two buckets instead of one, and the calculated mean time between failures shifts in ways that have nothing to do with actual equipment reliability.
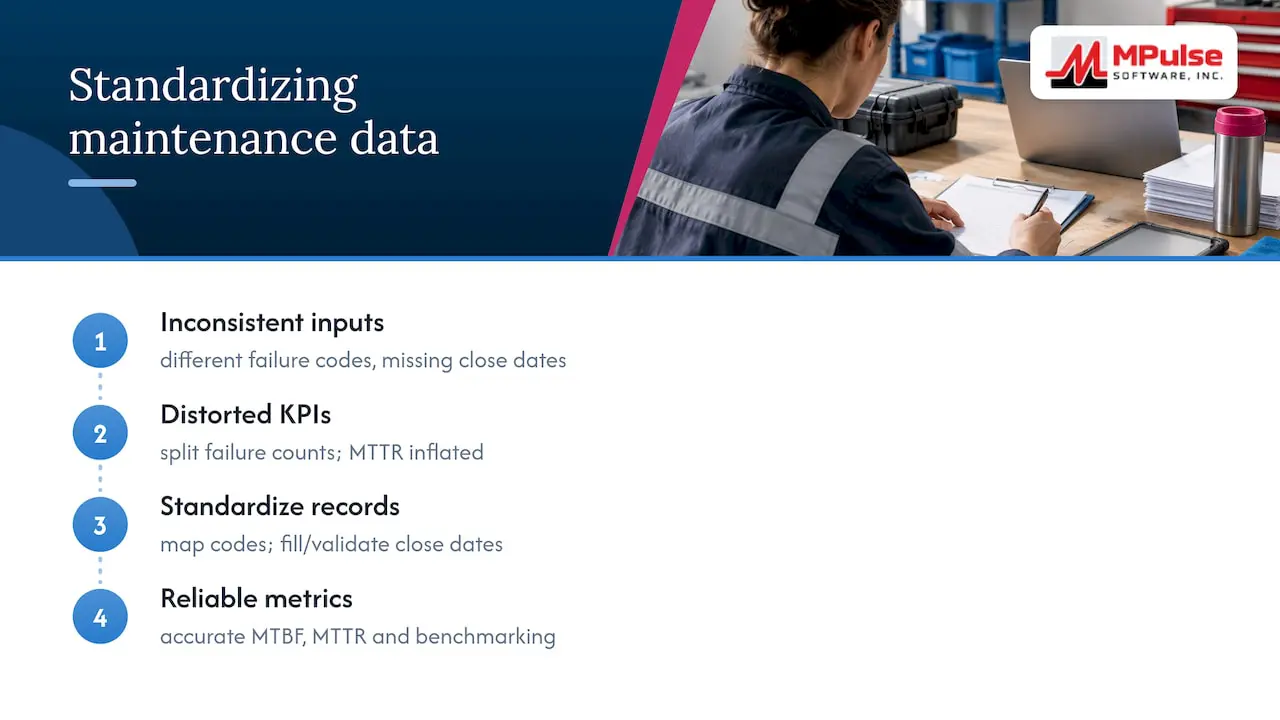
Missing close dates cause a similar problem. A work order left open for weeks after the repair was finished inflates MTTR, making a well-run site look worse than one that simply closes tickets faster on paper.
Inconsistent coding is a documented threat to KPI accuracy. A NIST case study examining historical HVAC maintenance work orders found that missing or censored fields distort reliability metrics, and that statistical correction methods are often needed before the data can support decisions. The business cost compounds from there: wrong MTBF numbers drive wrong prioritization, wasted spend on the wrong assets, and benchmarks that cannot be trusted across sites or against industry peers.
Standards and Reference Models Worth Building On
Maintenance teams do not need to invent a data model from scratch. Established standards already define the fields, taxonomies, and exchange formats that make cross-site and cross-industry comparison possible.
- ISO 14224 defines a structured taxonomy for equipment classes, failure modes, and maintenance data elements, built specifically to support reliability and maintenance data exchange across industries such as oil, gas, and process manufacturing.
- ISO 15926 and related neutral data models support system-to-system exchange, which matters when CMMS data needs to flow into ERP, asset management, or analytics platforms without losing meaning.
- SMRP metrics align event-type taxonomies with the reliability KPIs maintenance organizations already track, making it easier to map internal codes to an industry-recognized structure.
Adopting even part of one of these frameworks gives a maintenance program a defensible starting point instead of a home-grown code list that only makes sense to the people who built it.
Common Data Quality Problems That Block Standardization
Most standardization efforts stall on the same handful of issues, and recognizing them early saves months of rework.
- Overlapping or site-specific codes: the same failure described three different ways across three plants.
- Missing or censored timestamps: open dates without matching close dates, or costs logged against the wrong work order.
- Free-text overload: technicians writing narrative notes instead of selecting a structured code, leaving analysts to guess at meaning later.
- Dropdown fatigue: long, poorly organized code lists that push technicians toward the first option on the list just to close the ticket.
That last pattern is not random noise. Technicians under time pressure tend to select whatever is fastest, and that behavior produces systematic bias in the data rather than scattered errors that average out.
Pro Tip: Keep dropdown lists short and ordered by frequency of real use, not alphabetically, so the fastest choice is usually also the correct one.
Step-by-Step Implementation Roadmap
Standardization works best as a sequence, not a single rollout. Research on data-quality investigations recommends starting from the analytics outcomes a team actually needs, then auditing data against those needs before cleaning anything, a principle drawn from PHM Society proceedings on maintenance data quality.
- Define the target KPIs: decide which metrics, such as MTBF, MTTR, or schedule compliance, the data must support.
- Design a minimal data model: build asset taxonomy, event types, failure codes, and units around those KPIs, nothing more.
- Configure CMMS forms and mobile collection: enforce the model at the point of entry so technicians cannot bypass it.
- Pilot on one asset class or site: measure code completeness and KPI stability before expanding further.
- Train technicians and set entry rules: including clear exception handling for edge cases the model does not cover.
- Automate validation and dashboards: build feedback loops that flag incomplete or inconsistent records as they are created.
A small pilot before enterprise rollout is not optional caution. Guidance on asset data governance recommends testing on a limited scope first to confirm which fields actually drive the target KPIs before committing an organization to a new standard.
| Roadmap stage | Primary output | Where it’s implemented |
|---|---|---|
| Define KPIs | List of target metrics | Planning phase, with operations leadership |
| Design data model | Asset taxonomy and code lists | Data governance team |
| Configure CMMS | Enforced forms and mobile entry | CMMS asset records and work order setup |
| Pilot | Completeness and KPI stability results | One asset class or site |
| Train | Entry rules and exception handling | Technician workforce |
| Automate | Validation rules and dashboards | Ongoing operations |
Cleaning Up Legacy Maintenance Data for Analytics
Most organizations do not start with a blank slate. Years of inconsistent entries sit in the CMMS already, and throwing that history away wastes valuable failure records. A few methods make legacy data usable again.
- Exploratory data analysis (EDA) surfaces missingness patterns and correlated errors, showing which fields are unreliable and why before any correction begins.
- NLP and text-labeling (TLP) methods convert free-text notes into structured tags, recovering failure modes and work-type classifications that were never coded consistently in the first place, an approach demonstrated in research on maintenance data standardization for benchmarking and analytics.
- Imputation and survival analysis address missing or censored timestamps. The NIST HVAC case study applies survival analysis to correct censored closing dates and shows it can meaningfully change KPI estimates, though the assumptions behind it need to be reported transparently.
- Selective correction: not every flawed record deserves the same treatment. Weigh the impact on target KPIs against the cost of manual review, and tag or exclude records where correction is not worth the effort.
Governance That Keeps Standards From Decaying
A data model is only as good as the discipline that maintains it. Standardization without governance drifts back into inconsistency within a year or two.
- Assign stewardship roles: someone owns each data element and approves changes to code lists.
- Build a data-quality scorecard: track completeness, coding error rates, and time-to-close accuracy on a recurring basis.
- Schedule periodic audits: catch drift before it undermines KPI trust, and refresh technician training alongside it.
- Feed results into continuous improvement: scorecard trends should directly inform the next round of code list revisions.
This is also where benchmarking practices depend on standardized inputs staying standardized over time, not just at rollout.
How CMMS Features Support the Standardization Roadmap
A CMMS is the enforcement layer for everything above. MPulse CMMS applies this in a few concrete ways:
- Configurable work order templates enforce required fields for asset ID, failure code, and timestamps at data entry, closing the gap where technicians once skipped fields.
- Calendar-based scheduling for preventive maintenance reduces variance in work types, since PM tasks follow the same structure every cycle instead of being logged ad hoc.
- Integration capabilities, including the DataLink Integration Adapter, connect standardized CMMS data to ERP and sensor systems without translation errors.
- CMMS Implementation Services and MPulse CMMS Training give teams a structured path to configure the data model and train staff on the new entry rules.
What a Realistic Standardization Timeline Looks Like
Standardization rarely finishes in one project cycle. Expect iterative gains, prioritize the KPIs that matter most first, and resist the urge to lock every field down at once. Rigid forms that ignore real technician workflows get bypassed with workarounds. Pilot on the asset classes where bad data hurts the most, and expand from there.
— Mark
Getting Help Implementing a Standardization Program
Building a standardized data model takes configuration work, training, and integration effort that many maintenance teams would rather not build alone. MPulse offers a direct path through that work rather than a set of principles to figure out independently.
MPulse CMMS supports the roadmap above through a few specific offerings:
- CMMS software plans, including Professional and Advanced editions, priced at $29 and $79 per month per user respectively.
- CMMS Implementation Services to configure asset taxonomies, code lists, and work order templates around your target KPIs.
- MPulse CMMS Training to get technicians entering data consistently from day one.
- Integration add-ons, including the DataLink Integration Adapter, to connect standardized data to ERP and sensor systems.
Visit the MPulse services page to review implementation and training options, or check current pricing to find the plan that fits your rollout.
Sources
- The Impact of Data Quality on Maintenance Work Order Analysis: A Case Study in Historical HVAC Maintenance Work Orders | NIST
- Standardization of maintenance data for benchmarking and asset performance analytics (NIST/PHM related)
- PHM Society proceedings (data-quality and standards guidance)
- ISO 14224 preview (collection and exchange of reliability and maintenance data for equipment)
FAQ
What are the ISO standards for maintenance?
ISO 14224 is the primary reference for collecting and exchanging reliability and maintenance data across equipment types and industries. ISO 15926 supports broader system-to-system data exchange, which helps when maintenance data needs to flow into other platforms without losing structure.
What are the five C’s of data quality?
Definitions of the “five C’s” vary across sources and industries, so there is no single standardized list that applies specifically to maintenance data. Most maintenance-focused data-quality frameworks instead emphasize completeness, consistency, and accuracy of fields like failure codes and timestamps.
What is maintenance data?
Maintenance data is the set of records generated by work orders, including asset identifiers, event types, failure codes, timestamps, labor hours, and parts or cost information. Standardizing these fields across a data model is what allows KPIs like MTBF and MTTR to be calculated reliably.
What is the formula for standardization?
There is no single universal formula, since standardization depends on defining a consistent data model, code lists, and units rather than applying one calculation. The practical approach, recommended in PHM Society research, is to define target KPIs first, then build the minimal set of standardized fields needed to support them.